Dispatches from the Worlds of Digital Text
As we head into the fall semester, we wanted to share a round-up of our activities this past spring and summer — a particularly busy season for SEI.
We often approach talks and events as data-gathering exercises: opportunities to workshop our ideas before they’re formalized as research papers, and to observe the background, norms, and concerns of a new field. This season, we ventured deeper into communities we were already in touch with, such as type design and computer history, and into others completely new to us, like grapholinguistics. Read on for some of our key takeaways.
April: hosting local talks and the Unicode Technical Committee
We stayed in Berkeley in April, but many new folks came to us.
We were pleased to host our first visiting scholar, Bríd-Áine Parnell, PhD candidate at the University of Edinburgh. Bríd-Áine and I met somewhat serendipitously at the 4S conference in Seattle last September, in an afternoon of panels on text technologies. As the two people focused on the underlying standards driving textual expression on computers, we quickly found each other. Months later, we reconnected and arranged a visiting position in the Linguistics department at Berkeley, where she participated in standards meetings, interviewed experts, and ventured into the Unicode archives held at Stanford. Bríd-Áine wrote about her work and experience with us here.

We also co-organized a panel on the Adlam script with Prof. Adam Benkato in the Department of Middle Eastern Languages and Cultures. This was a happy confluence of interests: Adam was teaching an undergraduate class on writing systems (which I greatly enjoyed sitting in on), and it was nearing the topic of modern invented scripts just as we’ve been gearing up for a new research stream on the politics of such systems and their digitization. Together, we were glad to have Ibrahima and Abdoulaye Barry, inventors of the Adlam script for the Pulaar language used across West Africa, join us over two days for an in-class lecture and a public panel.
Adlam is one of the most celebrated recent script inventions, for its uptake across more than twenty countries, and its story has already been shared widely online. But it was fascinating to get new insights from the in-class discussion — like how the brothers had grown up hearing stories about people who tried to invent a script for the Pulaar language; how they themselves fought over the project direction; and how a “proper” name for the script only emerged when it came time for a Unicode encoding proposal.1

For the panel, we wanted to situate the case study of Adlam in different scholarly fields, to inspire more research in this direction and provoke new insights. After the Barry brothers shared their story, Coleman Donaldson, a linguistic anthropologist who has researched the N’Ko script, spoke on precursors to Adlam. He highlighted the longer history of script invention in West Africa, noting how Adlam grew up in the backyard of the N’Ko script, and sharing the philosophy of that script’s inventor, Solomana Kanté. I spoke on the panel about the challenges of bringing newly-invented scripts into digital systems. While Adlam had a wide base of evidence supporting its inclusion in standards like Unicode, not every script enjoys the same visible success. This creates a situation of decision-making under uncertainty, as standards-makers must bet that a script is widespread and stable enough to justify the hundreds of hours and resources required to implement it at the system level.
The panel helped to pry open the complex context and implications of invention, beyond the prevailing narrative of a script saving a people. I found myself leaving with a handful of new insights. For one, it hit home that prior to Adlam, many Fulani felt essentially as if they had an oral culture. While there was an official Latin orthography for the Pulaar language, schooling was done entirely in French. Adlam, and the educational system that arose alongside it, gave people a chance to gain literacy in their preferred language. I asked the Barry brothers whether they thought Adlam would have had as much success if there had been other options for Pulaar-language education, and they answered with a resounding no. As we think more about script competition and the conditions for neography (invented script) success, this feels like an important point to bear in mind.
Finally, the following week, we hosted the Unicode Technical Committee for its quarterly meeting.2 Unicode has often been hit with the accusation of being insular and stuck in Palo Alto.3 Now that’s not fair in every sense, but it must be conceded that the UTC meeting had not actually physically crossed the Bay in twenty years! 4 So it was a bit of an experiment bringing it to Berkeley.
This time, we saw in-person participation from folks we hadn’t seen in a long time, like Unicode veteran Ken Whistler, and got to use the opportunity to encourage more interaction with students and academics. We invited several colleagues who study the Unicode Standard to sit in, including Bríd-Áine, Raja Adal, and Keith Murphy. Linguistics chair Peter Jenks gave a welcome. Students from the Writing Systems class (who’d had an introduction to Unicode lecture the week prior from me) sat in on the scripts discussion and asked excellent, tough questions about how some scripts get selected to advance. Their other notable piece of feedback was for a gong to ring out every time a new addition was approved.
In addition to the usual UTC program, we arranged lunch talks on our ongoing research projects. This was a great opportunity to get feedback from the technical communities we are studying — a different but equally important test from academic peer review. Julian Vargo, a doctoral student in Hispanic linguistics, shared his work on evaluating font support for encoded scripts. Bríd-Áine introduced her work on bias in online name databases. And I shared a draft chapter from my book on Unicode’s development through the 80s and 90s. With mixed academic and industry audiences in the room, the result was a blend of seminar and standards-meeting conventions that pushed all the projects forward in valuable ways.
We are happy to be hosting again next spring. We are already thinking of how to keep encouraging the types of exchanges that took place in April, and use the occasion next year to mark SEI’s 25th anniversary.


May: delving into the international type design community
The next month, we dove deep into the type-design world at ATypI. The Association Typographique Internationale was founded in the post-war period to bring together European type foundries anxious to protect the rights to their work amidst disruption from new type technologies. Over the past half-century, it has gone through several expansions and iterations, arriving now as a global network of type designers concerned more than ever with language support and digital inclusion.
It was fitting that this year’s congress came to Stanford.5 Stanford is striking for having been the host of the famed 1983 seminar on digital typography (“The Computer and the Hand in Type Design”), and now for being home to the SILICON project, whose goal it is to advance the state of digitally-disadvantaged languages.

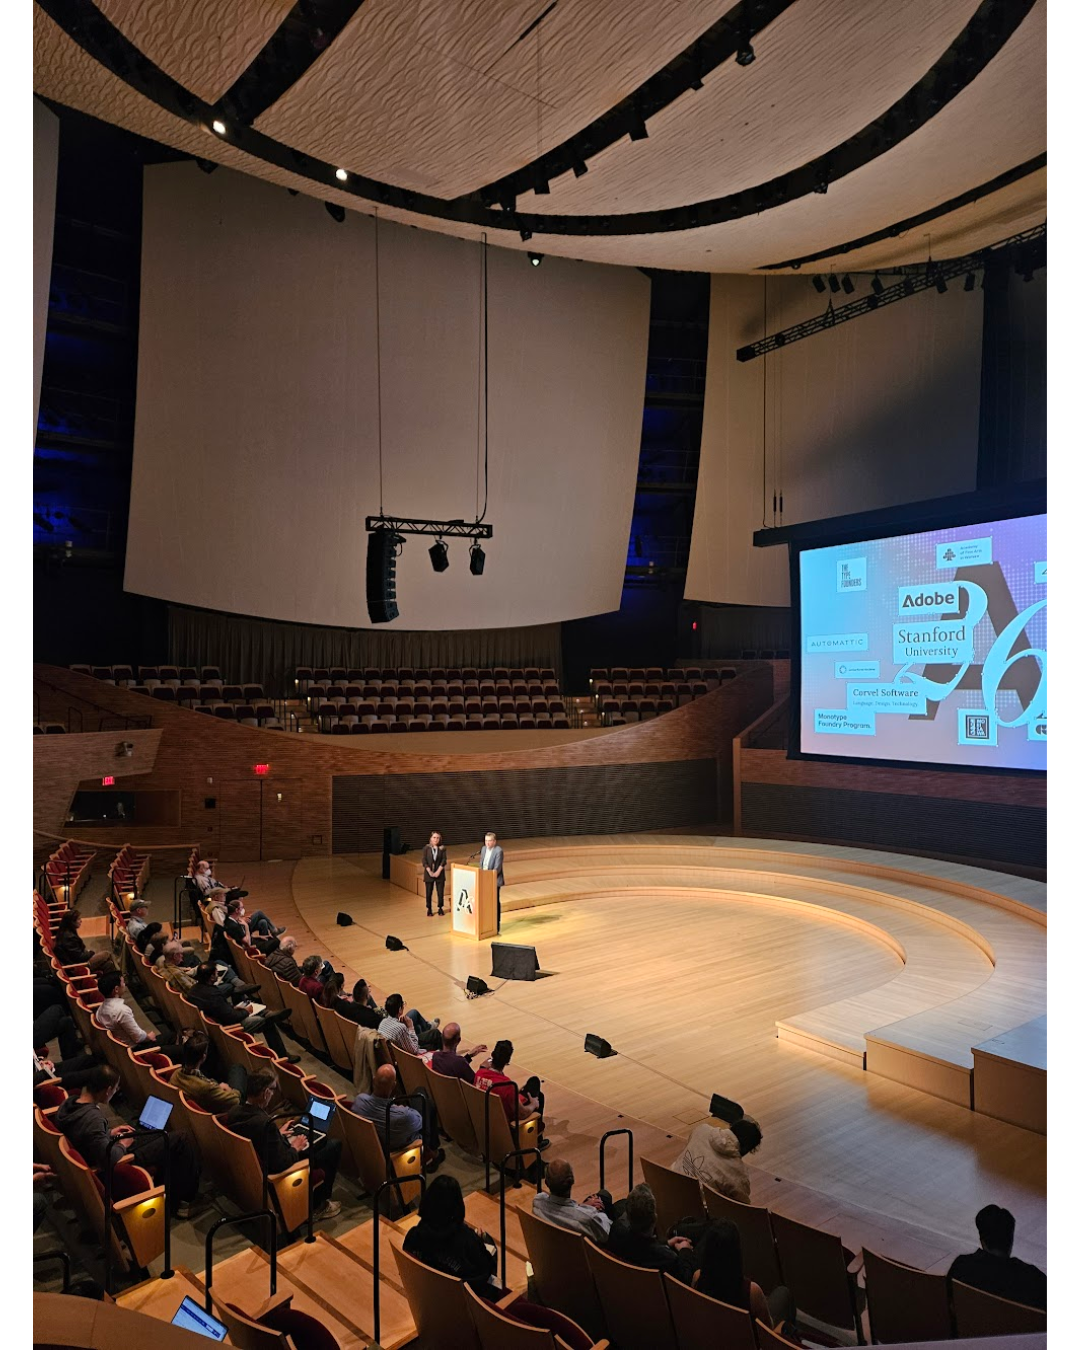


ATypI talks are consistently excellent, often carrying research on scripts that is hard to find anywhere else. When I was starting out as a graduate student, I watched dozens of recordings to get acquainted with the field. This year’s quality was no exception. Over several days of workshops and talks, we learned more about ATypI’s own history, probed the uncomfortable lineage of chop suey fonts, and traveled the world through work on Epi-Olmec, Meetei Mayek, the Yi scripts, and Maya hieroglyphs.
What struck me was how often encoding, keyboards, and other non-font technologies came up — a marked shift from previous years, when the focus had more often been on the craft of designing a digital font. I had felt a similar sense of transition around 2021, when I was virtually attending my first ATypI and it struck me as a “software-eating-the-world” moment. Google Fonts was the hot topic, and talk after talk reframed fonts as the small programs they really are, requiring bug-testing and clean, reproducible code, rather than just being treated as digital artworks.6
Our SEI team jumped actively into Q&A discussions alongside people from Bay Area tech companies, who could speak directly to where technical support might be improved to better serve a script community. Many of these conversations could have happened just as easily at the Unicode Technology Workshop — to me, a sign of how thoroughly these worlds are intertwining. That owes something to the venue, I think, and to the advocacy work SILICON has been doing across the type and tech sectors.
This environment proved more fitting than I’d anticipated for my own talk, on the “text stack.” The text stack, as I think of it, is an interlocking set of standards, software, and data all bent toward the single purpose of handling text in digital environments. Like the internet stack, no one part does everything, but work is delegated across the whole.

My argument was that whether or not we were conscious of it, most of us in that room were contributing to some layer of it. Naming the stack has real value in troubleshooting and innovation, letting us pinpoint which layer a problem lives in when text seems broken. But it may also help nurture an imagined community, one that can better communicate its shared purpose and needs, especially when it comes to resourcing.
I was glad to see the talk resonate with the room; some veterans of the field shared with me that they had been searching for language to describe the frameworks and experiences they had long worked within. In a way, it only made explicit a current already running through the conference itself: that making text work online is a multi-stakeholder, interdisciplinary endeavour, one that requires cooperation across vast communities of experts.


June: hopping from Berkeley to Paris to Reading
June opened close to home but soon took us over the Atlantic.
It started with the two-day conference of the Special Interest Group for Computing, Information, and Society (SIGCIS), hosted by UC Berkeley this year. This is a community that began with computer historians but has grown to include anthropologists, media theorists, and anyone probing the significance of computing in society. It’s the crowd my own work is most in conversation with, and it’s where I presented the talk-version of the book chapter I’d workshopped at UTC in April. I also took many notes on the interesting projects underway about computing’s entanglement with nationalism and globalization.

The standout in this vein was the keynote by Dwai Banerjee, drawing on his recent book Computing in the Age of Decolonization. He took beats from India’s computing history I recognized — the founding of the IITs, the indigenous computing push, License Raj — and marshalled them into an overarching argument about a postcolonial society striving to become sovereign. This was an exciting one for me to file away, as the account closes in the 1990s just as my own book project picks up, in some sense, on the same story in the 2000s.
The following week, our team had to split across two countries and three overlapping events. For the first half of the week, Debbie Anderson and I were in Paris for the International Organization for Standardization (ISO) meetings, while Helena Kansa was at Reading for the pre-workshops of Grafematik; in the second half, Debbie stayed on in Paris while I crossed the channel to join Helena for Grafematik’s main talks.
The Paris meeting was specifically for ISO/IEC 10646 Universal Character Set, a standard that runs parallel to Unicode.7
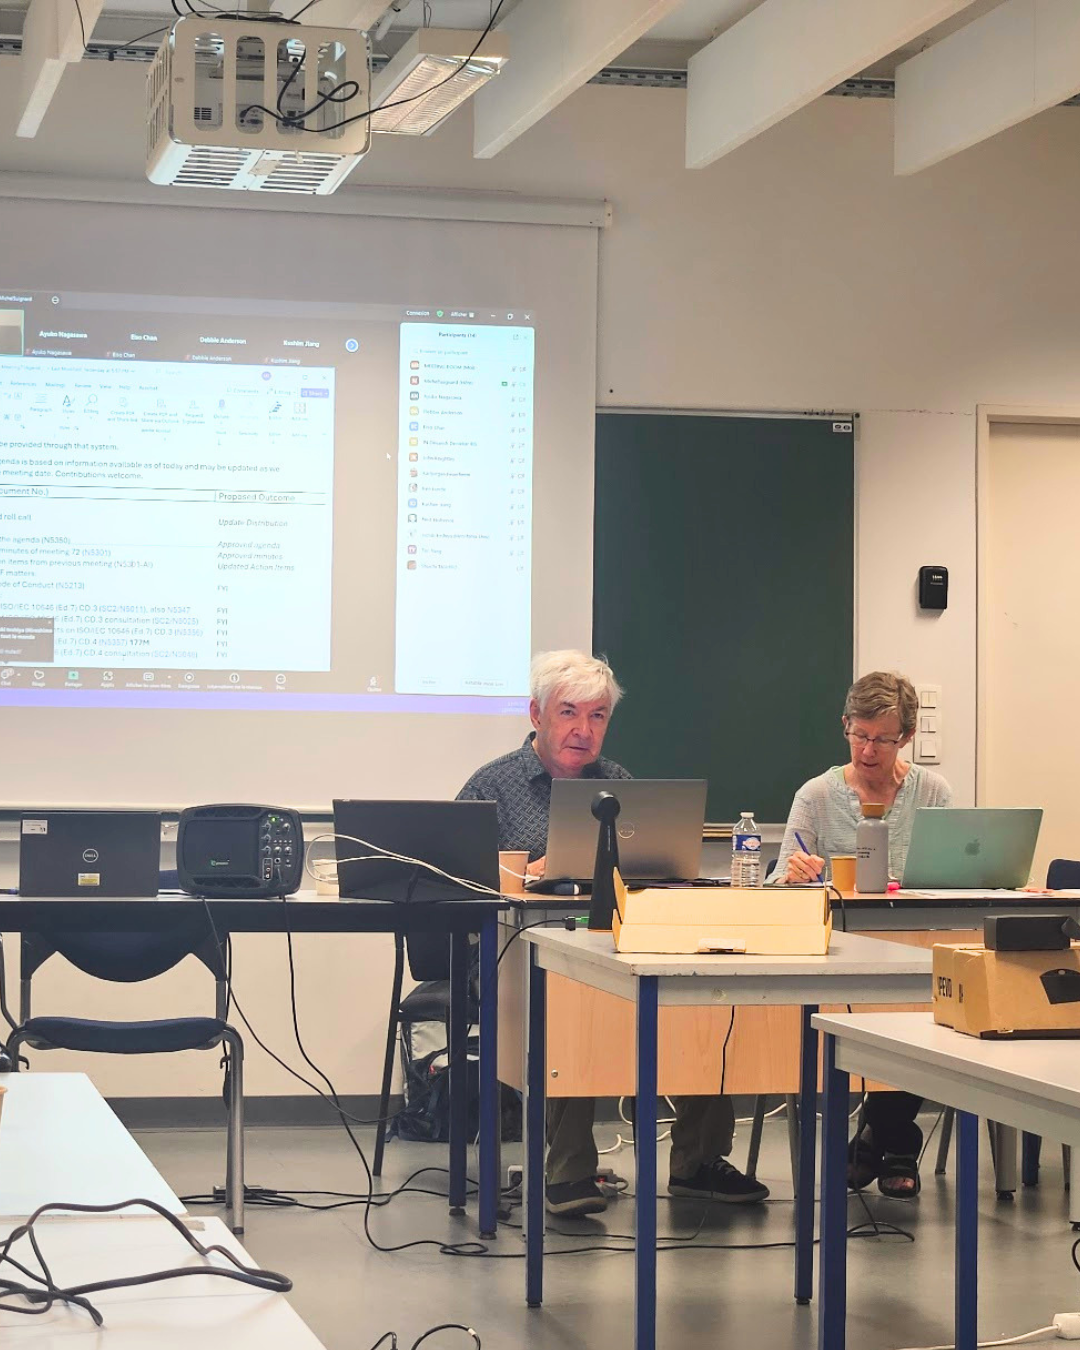

It should be noted that these discussions all occurred in the peak days of the first summer heat wave.
If the meeting room had air conditioning, we didn’t know it.
The dominant topic this year was a possible new model for the coordination between ISO and Unicode, in which the ISO character sets subcommittee establishes a “maintenance agency” (MA), a more nimble formation in which member countries and Unicode participate.
An MA is a mechanism often used by ISO when a standard requires frequent updates. At present, Unicode and ISO work on mismatched timelines. Unicode working groups meet as frequently as once a week, and release a standard annually. The ISO side meets only once a year and publishes no sooner than every two years. Keeping these standards in line is difficult and consequential, with major repercussions for international relations and software integrity if the synchronization fails.
The pitch for the MA is that a smaller joint group of national-body and Unicode representatives could allow the two bodies to interact more often and cut down on duplicated efforts, like producing the code charts twice.
This sounds good, but the devil is of course in the details. Any workable structure has to leave national bodies satisfied with their standing, make the process more efficient and more participatory rather than trading one for the other, and be robust to new countries and new personalities entering the mix.
To me, these discussions were the culmination of the tensions begun in 1988-91, when there were two unsynced standards with dramatically different understandings of what an architecture for a universal character code could be. Like now, there were different strengths and expertise involved in either effort. But unlike now, there was far broader participation from national bodies in ISO and a true sense in which “text handling” was an urgent problem that needed to be solved. That isn’t the case anymore — these standards have succeeded. The two standards have also since diverged in scope, altering the balance of responsibility. The character code is now only one of Unicode’s many projects, the others geared towards actual implementation, and it is on that work that the ISO code charts now depend.
I find it striking to watch the question first posed around 1990 — what should the relationship between these two bodies actually be? — now get a fresh attempt at a response. If things move quickly on a standards timeline, we may yet get an answer by the end of the decade.
It should be noted that these discussions all occurred in the peak days of the first summer heat wave. If the meeting room had air conditioning, we didn’t know it. Liang Hai bought a fan on day 2 and we herded ourselves into the half of the room it could reach with any might.

Our adventures came to a close with the Grapholinguistics in the 21st Century conference (also known as “Grafematik”), held at the University of Reading. Reading is known for its type research program and its specialization in non-Latin scripts, and the Grafematik program revealed that influence, which leaned towards type history as much as the study of writing itself.
At this conference, I delivered a talk on a joint paper with our Missing Scripts colleagues Johannes Bergerhausen and Thomas Huot-Marchand, entitled “A Text Processing Theory of Script.” The idea emerged from our discussions around the World’s Writing Systems (WWS) poster, and how we decide what earns a spot on it and what doesn’t. We realized that for the naming and selection of scripts, we were defaulting to the logic of the Unicode Standard — if it gets its own code block, it gets a glyph on the WWS. More interestingly, that Unicode-based logic did not map cleanly onto other prevailing logics for script classification or identification, whether typographic, palaeographic, linguistic, or socio-political.

So we set out to name this Unicode-based logic, and to assert that doing so is not merely an intellectual exercise in coining yet another term, but a framing worth recognizing because it has operative power in the world, shaping human existence online and elsewhere. In the talk, we traced how Unicode’s interpretation of text-processing — things like searching and sorting text, typing and displaying it — had itself evolved over time, making it something of a moving target for observers.
Grapholinguistics, the study of written language, is a relatively young field, but it has already produced a vibrant literature. In preparing for the talk, it was a pleasure to dive into Demetrios Meletis’ ambitious work toward defining a common vocabulary for the field, Yannis Haralambous’ analyses of Unicode from its earliest days, and Christa Dürscheid’s consideration of Unicode as a kind of script museum.
At the conference itself, there were several fascinating threads to follow. Keith Murphy picked up the Unicode thread in his paper on how script encoders turn “chaos into order,” prompting a lively discussion. Irmi Wachendorff took us into a “typographic landscapes” study of how Blackletter is understood in European cities today — a script once strongly associated with German nationalism and now, she finds, being reclaimed to the opposite end.8 Amalia Gnanadesikan offered an intriguing framework for understanding script use. Just as we have native tongues (L1), she proposed, there is such a thing as a “native script” (S1). But unlike secondary languages (L2), she found it exceedingly difficult for an S2 script to come into everyday use, since S1 scripts tend to be so well-institutionalized.


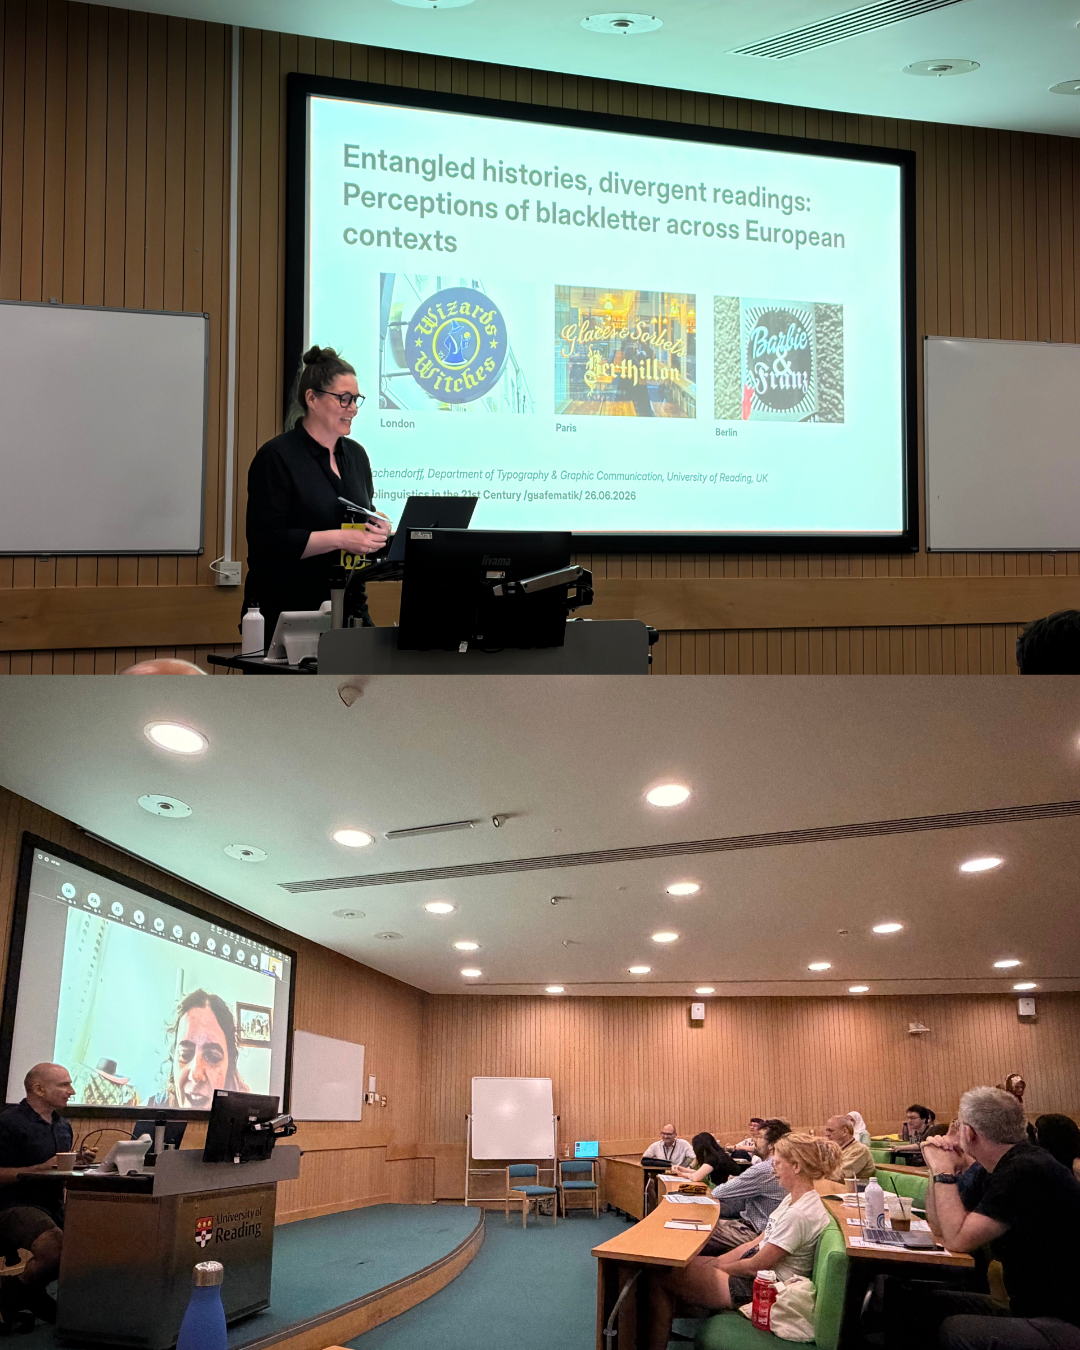


This framework really struck me, and helped me understand both Adlam’s runaway success and the more limited use of most other neographies. Pulaar had no well-established S1 for Adlam to displace, so the script could claim that spot for itself. Most neographies, by contrast, emerge where a dominant script already sits, and “success” often amounts to symbolic use — slogans, signs — rather than everyday writing.9
When I asked Amalia what a new script could do if it genuinely wanted to compete against an entrenched S1, her answer was to look at schooling. If education is administered in the new script, it might have a chance, pointing towards the same understanding the Barry brothers shared back in April.
We’ll be carrying these lessons into our ongoing study of neographies and how Unicode contends with them.
Overall, this was a whirlwind of a season. We traipsed from Berkeley to Stanford, then on to Paris and Reading, through communities as ostensibly dissimilar as type designers, computer historians, grapholinguists, and standards diplomats, but found common preoccupations lurking within each. It was astonishing how often we caught echoes of one in another. An early insight from the Adlam panel became a moment of clarity at Grafematik; a dive into Unicode history for my UTC lunch talk gave me perspective on the maintenance agency question playing out at ISO. We left with the feeling that there is really one conversation happening, whether the participants know it or not. Our hope at SEI is to bring them into the same room, and help them learn to speak a little of the same language.
- Until then, they had used the shorthand “Bindi Pulaar”, which meant simply “Pulaar script.” The naming opportunity sent them back to the community, which came up with the acronym ADLaM, drawing from the first four letters of the script and standing for Alkule Dandayɗe Leñol Mulugol, or “the alphabet that protects a people from vanishing.” ↩︎
- These meetings bring together all the technical experts working on the Unicode Standard — from the scripts working group we’re most involved in, to the emoji group, to properties, language data, and more. Each group works independently on its own schedule, meeting anywhere from weekly to monthly (with considerable overlap in participants), and then shares updates during the three days of UTC. ↩︎
- Here’s one example from our friend, Gerry Leonidas. ↩︎
- It does get out to other parts of the West Coast, though, and will actually be crossing an ocean to be held in Nancy, France this very October, to co-locate with the Unicode Technology Workshop. ↩︎
- For the first time, the annual congress is being held in two locations — spring at Stanford, and fall in Sharjah. ↩︎
- Even earlier, and more explicit, transitions were of course the 1983 Stanford seminar on digital typography, and even before that, the 1979 congress in Prague on “Typographic Opportunities in the Computer Age.” ↩︎
- Specifically, these were the meetings of Joint Technical Committee 1 (JTC1) – Subcommittee 2 (SC2) and Working Group 2 (WG2). Similar to the Unicode Script Encoding Working Group, the role of WG2 is to review script proposals and give recommendations for SC2 (similar to the UTC). SEI’s role here is as a direct liaison to WG2, the group of independent experts, so we give a short report on our annual activities. Debbie is also the chair of the US national body in SC2, and I serve as an alternate. ↩︎
- Typographic landscapes is related to the earlier tradition of linguistic landscapes. The latter calls to analyze the linguistic mix of a culture by observing language (and script) use in public spaces, like street signs and shop logos. Typographic landscapes brings semiotics into the mix and attends to what specific typographic choices are indexing. ↩︎
- For examples, see work by Nishaant Choksi on Ol Chiki or by Adeli Block on neo-Tifinagh. ↩︎